A talk in three parts
Speech Models
past, present and the future
The past
Making machines talk, from bellows to APIs
The present
Tokens, transformers and training like a language model
The future
Knowing what good sounds like
Then · PlayAI
Now · Meta
Research engineer on Muse Voice
 x.com/nishnik
Part one
The Initial Phase
Making machines talk, from bellows to cloud APIs, 1779 to 2018
x.com/nishnik x.com/nishnik
Part two
The Present
Tokens, transformers and training like a language model
x.com/nishnikThe present
Tortoise
An open-source model that borrowed its idea from image generation: turn the medium into tokens, predict the tokens, then render them back.
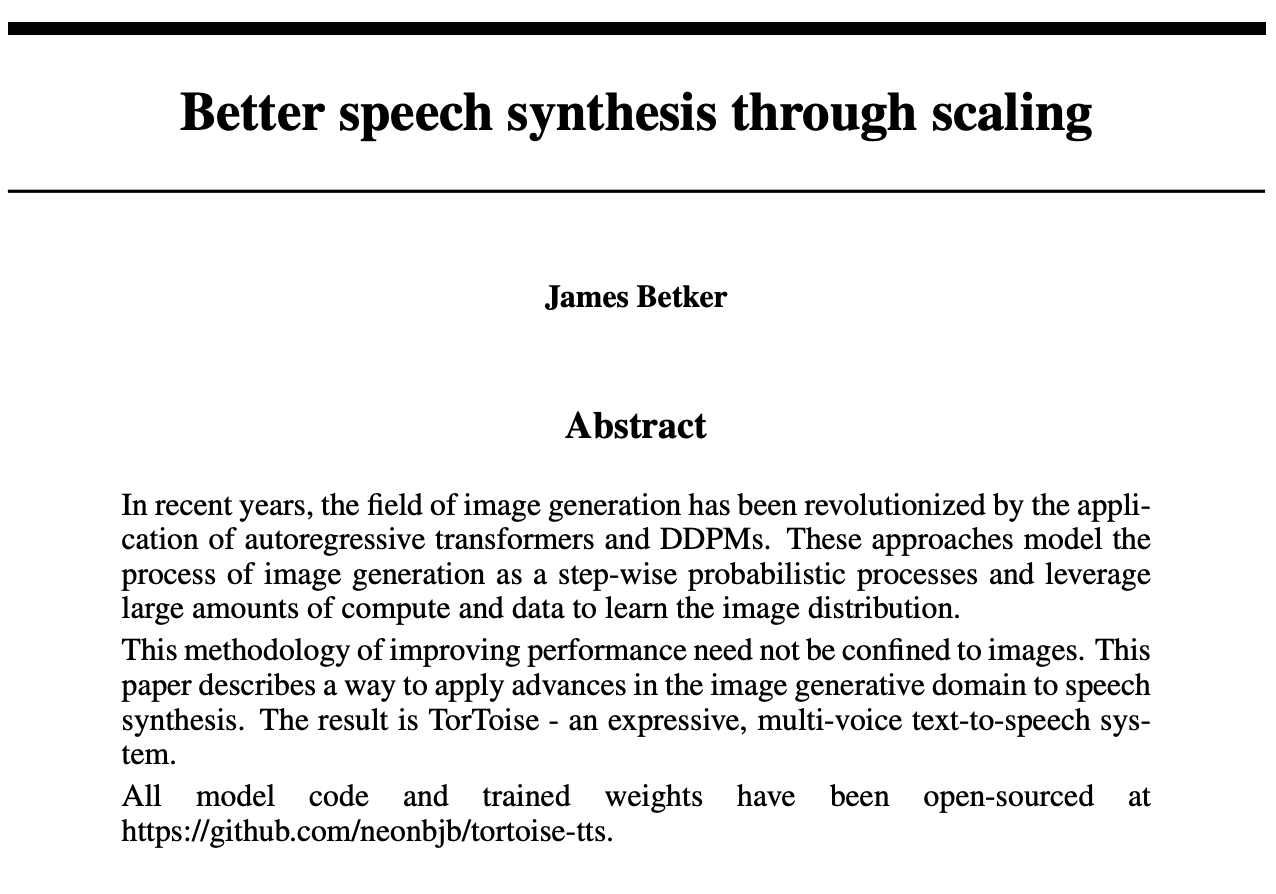
Betker, “Better speech synthesis through scaling”, arXiv, 2023
tokens
predict
render
Tortoise
Encode, Model, Decode
Box one
Encode
Waveform in, codes in the middle, waveform out.
A VQ-VAE with 8,192 codes
Box two
Model
The same codes, predicted one at a time.
GPT-2 style, 30 layers
Box three
Decode
Codes in, waveform out.
Diffusion, then a vocoder
Text to Speech: past, present and the future
The present
x.com/nishnikOpen models today · PlayAI · 2025
PlayDiffusion: edit one word, keep the rest
Encode
XLS-R
Speech becomes discrete XLS-R tokens; the span to change is masked out.
Model
Llama-style
A pretrained text transformer, made non-causal, fills the masked tokens from both sides.
Decode
BigVGAN
A custom-trained BigVGAN turns tokens into audio, with the original speaker’s embedding.
Source: PlayDiffusion model card, huggingface.co/PlayHT/PlayDiffusion (Apache-2.0)
5 of 5
x.com/nishnikOpen models today · Kyutai · July 2025
Kyutai TTS
Encode
12.5 Hz
Mimi, the streaming codec from Moshi: semantic and acoustic codes together.
Model
1.6B
A 1B backbone over time plus a 600M depth transformer over each frame’s codes.
Decode
Streaming
Text runs about 1.28 s ahead, so speech starts before the full text arrives.
Sources: kyutai.org/tts (1.6B, July 2025) · BuilderAI, July 2026 (1B + 600M, 1.28 s) · Moshi paper (Mimi)
2 of 5
x.com/nishnikThe parallel
The same three boxes as a text LLM
Text to Speech: past, present and the future
The present
x.com/nishnikCompared with text LLMs
Where speech is harder than text
The knowledge is in text
Proofs, code and most of science are written, not spoken. Audio alone hits a ceiling on world knowledge.
Text takes turns; speech overlaps
Chat is one message after another. Talk has backchannels, interruptions and meaningful pauses.
Many more tokens
About 3 text tokens per second of speech, but 100 Mimi tokens: longer sequences, costlier context.
Text to Speech: past, present and the future
The present
x.com/nishnikAnyway, we merge with the LLM
One model now reads, sees, hears and speaks
GPT-4o
OpenAI · May 2024
One network for text, vision and audio; voice replies in 320 ms on average
Gemini
Google · Dec 2023
Trained multimodal from the start: text, images, audio and video
Qwen3-Omni
Alibaba · Sep 2025
A Thinker reads everything; a Talker speaks. 30B total, 3B active
MiniCPM-o 4.5
OpenBMB · Apr 2026
9B: SigLIP and Whisper encoders into Qwen3-8B; full duplex
Sources: OpenAI, Hello GPT-4o (2024); Gemini report (2023); arXiv 2509.17765; arXiv 2604.27393
The present
x.com/nishnikThe recipe
Trained in four stages, like a language model
Structure after Andrej Karpathy, “State of GPT” (2023)
The present
x.com/nishnikMerged, but real time has a budget
A small model talks. A big model thinks.
Human turn gap
~200 ms
The usual pause before someone answers, across languages
What fits in the call
3B active
Qwen3-Omni: 30B total, 234 ms to the first audio
What thinks in the background
GPT-5.5
GPT-Live hands reasoning and tools to it, off the audio path
Sources: OpenAI, Introducing GPT-Live (Jul 2026) and delegation guide; Stivers et al., PNAS 2009; arXiv 2509.17765
The present
x.com/nishnikPart three
The Future
Post-training is where the money goes
x.com/nishnikWhere the compute goes
RL went from a rounding error to pretraining scale
10×
RL compute from o1 to o3, about four months apart
≈ 4×
growth of all frontier training compute per year
Chart redrawn from Epoch AI, “How far can reasoning models scale?” (May 2025) and xAI’s Grok 4 post (July 2025)
The future
x.com/nishnikStability and preference, measured
RL already pays off in speech
The catch: reward hacking
To cut WER, Seed-TTS learned to talk slower and over-clearly, and lost naturalness.
Others doing it
Qwen3-TTS (DPO, then GSPO), IndexTTS 2.5 and GLM-TTS (GRPO). Graders: ASR error, speaker similarity, emotion classifiers.
Sources: arXiv 2406.02430 (Seed-TTS), 2505.17589 (CosyVoice 3), 2502.05236 (Koel-TTS), 2504.02407 (F5R-TTS)
The future
x.com/nishnikFull duplex: RL on timing
RL can also teach when to speak
Moshi, aligned on real chats
Kyutai · Jun 2025 · offline DPO
283K preference pairs from live users. An LLM judge flags bad answers and bad timing: cutting the user off, or not answering.
QA 36.1 → 39.2 · Safety 70.9 → 77.8
DuplexPO: RL only for timing
NTU, NTU Taiwan, NVIDIA · Jul 2026 · GRPO
A reward per event: start on time, backchannel on cue, yield to a barge-in. What it says stays put.
Turn delay 7.3 s → 0.24 s · Yields to barge-in 65% → 100%
Sources: arXiv 2506.21463 (Kyutai); arXiv 2607.07148 (DuplexPO). Animation is an illustration.
The future
x.com/nishnikWhat TTS has
TTS RL has a few numbers and one task
Graders
Mostly metrics
WER / CER from a recognizer
Speaker similarity
Predicted MOS (UTMOS)
Emotion classifier
A/B preference reward model
Audio events (laughter)
Environments
Read this line
Single turn: text in, score the audio
Emerging
Style instructions + audio judge
Simulated-user conversations (SpeechGym)
Long-form consistency
Examples: Qwen3-TTS (DPO, GSPO), GLM-TTS (GRPO), IndexTTS 2.5 (GRPO), CosyVoice 3 (DiffRO)
The future
x.com/nishnikGrading conversation
Duplex graders exist: good proxies, still coarse
Heuristics you can reward
Takeover rate during the user’s pauses
Backchannel frequency, per second
Backchannel timing vs humans (JSD)
Response latency when taking the turn
After an interruption: relevance (LLM judge) and latency
Moshi on these heuristics
| Test | Moshi |
|---|---|
| Takeover in pauses | 0.985 (lower is better) |
| Backchannels per second | 0.001 |
| Backchannel timing JSD | 0.957 (lower is better) |
| Turn-taking latency | 0.265 s |
Source: Full-Duplex-Bench, arXiv 2503.04721 (Table III, synthetic set); critique example is illustrative
The future
x.com/nishnikFrom one reward to the whole trajectory
Code RL grades every step. Voice grades one moment.
Rubric judge for SWE agents
ByteDance Seed · Mar 2026
36.6% → 42.6%
SWE-bench Verified: tests only vs. a rubric judge scoring every turn
SWE-TRACE
vivo · Apr 2026
pass/fail → rubric
Pass/fail treats every success alike; a per-issue rubric scores the whole run
SpeechGym, in voice
UIUC + Amazon · Aug 2026
16% → 99.6%
Training groups that carry signal: outcome only vs. a reward per tool call
Sources: arXiv 2604.16335, 2604.14820, 2608.26432. Scores in the animation are illustrative.
The future
x.com/nishnikThe future
Three numbers cannot grade a conversation
Graded today
Three numbers
- Word error rate
- Speaker similarity
- Audio quality
A flat, correct reading scores perfectly on all three.
What a voice environment should grade
A finer rubric
- Emphasis on the right word
- Pauses and pacing
- Turn-taking
- Backchannels
- Emotion that fits
- Names and numbers
- Consistency over time
- Handling interruptions
Text to Speech: past, present and the future
The future
x.com/nishnikWhat text has
Text RL has many graders and many worlds
Graders
What gives the reward
Exact-answer checkers (math)
Unit tests and execution
Proof checkers (Lean)
Preference reward models
LLM judges with rubrics
AI feedback from principles
Format and safety rules
Task outcomes for agents
Environments
Where the model acts
Math with verifiable answers
Code repos with tests
Terminal and shell tasks
Browsers and computer use
Tool calls with simulated users
Formal theorem proving
Deep research and search
Multi-turn chat
Examples: SWE-bench, Terminal-Bench, WebArena, OSWorld, τ-bench, miniF2F
The future
x.com/nishnikEnvironments you can download
Code has thousands of environments. Voice has ??
7,780
MiMo-V2.6 RL environments: code, terminal, cyber, web dev and more
5.5K+
SmolDataEnvs code and data tasks, graded without an LLM judge
1 gym
SpeechGym (Aug 2026), 4 spoken domains. The rest are evals
Sources: FineEnvs RL Explorer, Hugging Face; Fan et al., SpeechGym, arXiv 2608.26432
The future
x.com/nishnikVoice agents · what exists today
Mostly evals. We need environments to hill-climb.
RL environment
SpeechGym
UIUC + Amazon · Aug 2026
24% → 53%
τ-Voice pass@1 after GRPO. Reset, step, reward: two omni models talk through 4 spoken domains.
Its interface takes any text agent domain and any open omni model.
Evals: a score, not a training loop
τ-Voice
Sierra · Mar 2026
≤ 38%
Voice with noise and accents; text gets 85%
Full-Duplex-Bench v2
Feb 2026
Live examiner
An AI examiner talks; an LLM judge scores
Jarvis Bench v0.5
Voice Arena · Sep 2026
vs humans
Agents vs people: job done, and sounding natural
Full-Duplex-Bench v3
Apr 2026
5 × 4
Tool calls with real disfluency, 4 domains
VoiceAgentBench
Krutrim AI · Oct 2025
5,757
Spoken tool calls in 7 languages
MP-Bench
Shih et al. · Sep 2026
≤ 22%
Multiparty: when not to speak?
Sources: arXiv 2608.26432, 2603.13686, 2604.04847, 2510.07978, 2609.13076; Full-Duplex-Bench; Voice Arena
The future
x.com/nishnikTo close
The past
Making machines talk.
The present
Training them like language models.
The future
Knowing what good sounds like.
Connect on X
Nishant Nikhil
x.com/nishnik
x.com/nishnikSources
Papers and reports behind the talk
Models and codecs
- Tortoise TTS (Betker)
- Descript Audio Codec (DAC)
- Moshi and the Mimi codec (Kyutai)
- MAVE: Mamba-based TTS
- PlayDiffusion (PlayAI)
- BigVGAN (NVIDIA)
Speech inside LLMs
- CosyVoice 2 and CosyVoice 3
- Sesame CSM
- PersonaPlex (NVIDIA)
- Inworld TTS-1
- Karpathy, “State of GPT” (2023)
RL and environments
- GRPO for LLM-based TTS
- Koel-TTS (NVIDIA)
- Multi-Reward GRPO
- RRPO, on reward hacking
- Epoch AI, citing The Information
- Hugging Face blog, citing Nathan Lambert
Text to Speech: past, present and the future
Sources
x.com/nishnik